
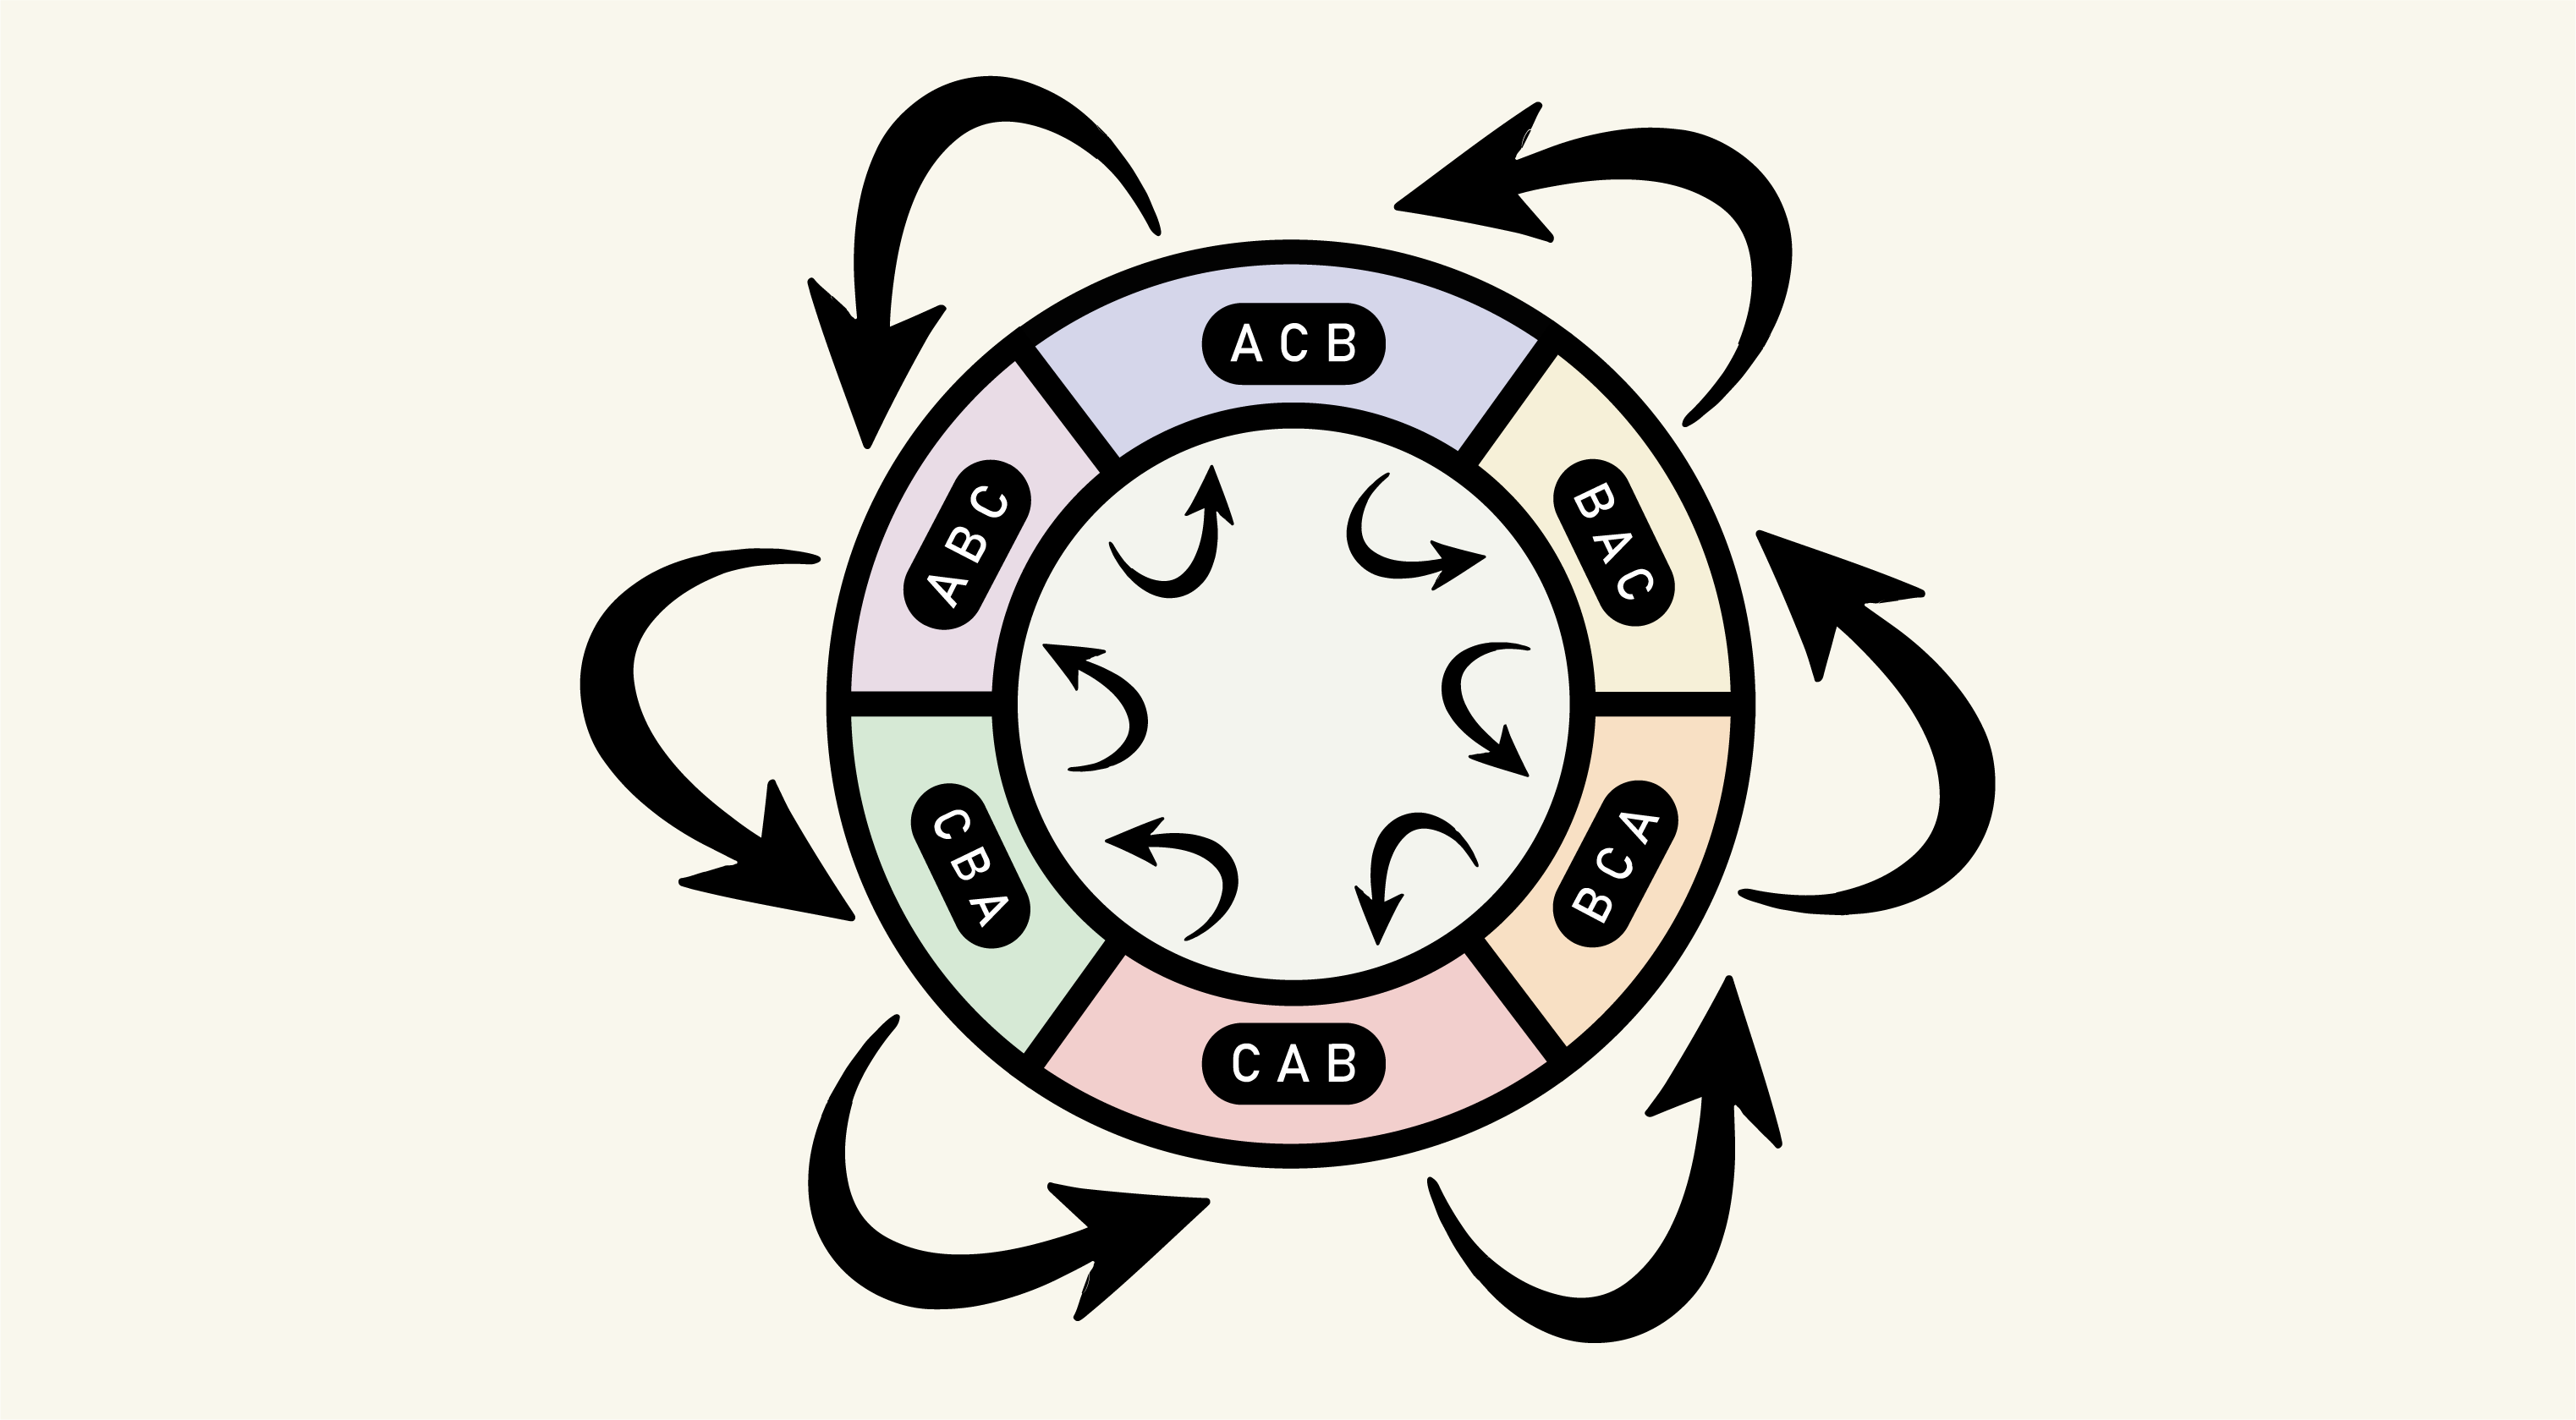
IntroductionIn this article, I am going to present a novel approach for merging several sorted sequences into one called guided K-merge and, based on that, a general-purpose sorting algorithm called guided K-merge sort.The current approaches to efficient merging of several sorted sequences require some helper data structures, such as a sorted array or a priority queue. In contrast, guided K-merge keeps the required information with the help of multiple isomorphic code fragments, and uses the goto operator to jump between them.Theoretical evaluation shows that guided K-merge reduces the time for such a multi-way merge, compared to the current implementation that uses a sorted array. At the same time, guided K-merge doesn’t introduce any overhead, in contrast to the current implementation that uses a priority queue.Based on all that, the practical evaluation shows that depending on the type of data being sorted, guided K-merge sort can perform up to 15% faster, compared to the widely used merge sort algorithm.This article is organized as follows:Table of contentsIntroduction1. Recalling merge, merge sort, and K-merge sort algorithmsRecalling the merge sort algorithmRecalling the K-merge sort algorithm2. The guided merge procedure3. Implementation of guided merge procedure4. The guided merge sort algorithm5. Theoretical evaluationEvaluation of K-mergeEvaluation of guided K-mergeComparison between K-merge sort and guided K-merge sort6. Practical evaluationSummary of the resultsBenchmarking7. ConclusionReferences···1. Recalling merge, merge sort, and K-merge sort algorithmsSorting a sequence of values is an essential procedure in Computer science. Given an arbitrary sequence, after running any sorting algorithm on it, we expect all its values to be rearranged – most of the time in increasing order:Example of an input sequence (top series) and the same set of values after being sorted (bottom series).The necessity to sort arises, for example, when we need to:efficiently navigate over large volumes of data, and find necessary items there;present existing data to the end-users in a clearer way;identify certain patterns in large volumes of data;… and in many other cases arising in different fields.There are different sorting algorithms, most famous of which are probably bubble sort, quick sort, and merge sort, each having its relatively strong and weak sides.Merge sort (or some variation of it) is often the default sorting algorithm in standard libraries of various programming languages. For example:Java uses merge sort when sorting an array of non-primitive data types,Python uses Timsort, which is a combination of merge sort and insertion sort algorithms,C++ uses merge sort (or some variation of it) when the sorting must be stable.Recalling the merge sort algorithmUnderstanding the merge procedure and merge sort algorithm is important for proceeding with this article. There are many good tutorials and videos on the Web, such as [1], [2] and [3]. This sub-section will also help recall them.Merge sort is a recursive algorithm, the building block of which is the merge procedure. Given two already sorted sequences, the purpose of merge is to combine them into one, preserving the sorted state in the result:Example of a merge procedure. At the input, there are two sorted sequences ‘A’ and ‘B’ (top series), values of which are combined into one sorted sequence (bottom series).Within the merge procedure, both input sequences ‘A’ and ‘B’ arrive in sorted order. This means that after the merge, values of ‘A’ will preserve their relative order in the output sequence, as well as values of ‘B’ will:All values of either input sequence preserve their relative order after being merged. We can easily check it, as the curved dashed arrows (which identify movement of values from input to the output) do not intersect.This fact allows us to produce the output sequence from left to right, while scanning both input sequences in parallel, also from left to right.The merge procedure is in progress. The directions of scans are presented with thick gray arrows. The next value under consideration from ‘A’ is “A[2] == 12”, and the next value under consideration from ‘B’ is “B[3] == 16”. The value from ‘A’ is smaller, which is why it is taken to the output sequence.At every step, we will just compare the next value of ‘A’ with the next value of ‘B’, and take the smaller one into ‘Out’.Close to the finish, one of the sequences will be completely moved to the output, while some short fragment will remain in the other one. It means the values of the remaining fragment are greater than all the values already considered, so we can just copy it to the output.The merge procedure is close to completion. All values from sequence ‘B’ are already placed into the output, while 2 rightmost values from ‘A’ remain. This means they are greater than all values of ‘B’, which is why we just copy them to the output (the 2 dashed curved arrows) at the end.The code for the merge procedure in C++ becomes:The time complexity of merge is always O(n1+n2), where ‘n1’ and ‘n2’ are the lengths of the input sequences. That’s because all the “n1+n2” values need to be copied (or moved) to the output, and every copy is performed in a constant amount of time.Now, the merge procedure outputs a sorted sequence, but it requires the input sequences to be sorted too. How can we use merge then to sort an arbitrary input array? The answer is: using recursion, and that is how the merge sort algorithm operates. What it does to sort an n-long input sequence is:divides it into 2 equal parts (halves),recursively sorts each half, in an independent manner,merges the sorted halves into the result array.High-level illustration of the merge sort algorithm. Given an unsorted sequence (top series), the algorithm divides it in 2 [almost] equal parts, recursively sorts each of them (the figurative gearboxes), and after having 2 sorted halves, merges them into one output sequence (bottom series).This means that, when recursively sorting the left half, it will also be divided into 2 equal parts (each being a quarter now), each of which will be sorted recursively, before being merged into the sorted left half. The same also refers to the right half of the sequence.Merge sort illustrated with the recursion depth of 2, where we can see how each of the halves is being sorted. Either half is evenly divided into quarters, each of which is sorted recursively and independently from each other (the 4 figurative gearboxes). After having 4 sorted quarters, the leftmost 2 quarters are being merged, as well as the rightmost 2 quarters. That produces 2 sorted halves, which are being merged during the final stage.This way, while recursion deepens, the current sub-array that should be sorted is shortened twice. The recursion stops when the algorithm reaches a 1-element sub-array, which, obviously, does not require any sorting. Some optimizations stop recursion sooner, once the current sub-array becomes shorter than a predefined threshold, after which they switch to a simpler sorting algorithm, often to insertion sort.The code of the merge sort algorithm in C++ becomes:As we see, merge sort uses a temporary buffer to store the output of the merge procedure. This is required, as we can’t write the merged sequence into the same memory location from which we read either of its input sequences ‘A’ or ‘B’. That’s why, on every invocation of “merge_sort”, first we write the merged sequence into the temporary buffer, and then copy it back to the original array ‘X’.There is an optimization called ping-pong merge sort, which, when applied, eliminates such copying back almost entirely. It does that by repeatedly swapping the roles of ‘X’ and ‘buffer’. Briefly speaking, on the even levels of recursion it merges intermediate results from ‘X’ to ‘buffer’, while on the odd levels of recursion it merges them from ‘buffer’ back to ‘X’. However, for simplicity, we don’t implement the ping-pong optimization in this paper.Recalling the K-merge sort algorithmThe algorithm that I am going to describe is in fact an optimization of one variation of merge sort, which is called K-merge sort. The difference between merge sort and K-merge sort is in how many equal parts the sequence is divided into. If merge sort always divides it into 2 parts, then what K-merge sort does is:divide the input sequence into K equal parts,recursively sort them in an independent way (applying K-merge sort to each of those parts),combine the K sorted sequences into one, using the K-merge procedure.High-level illustration of the K-merge sort algorithm. Given an unsorted sequence (top series), the algorithm divides it into ‘K’ [almost] equal parts, recursively sorts each of them (the figurative gearboxes), and after having ‘K’ sorted parts, merges them into one output sequence (bottom series), using the K-merge procedure.The advantage of K-merge sort over ordinary merge sort is the decrease in recursion depth. On every level, merge sort splits the current range into halves, which, for an n-long input sequence, requires “log2n” levels to reach the 1-long sub-range, thus, to reach the exit branch of recursion:A complete “workspace” of the merge sort algorithm. We see that every sub-range of a current level is divided into 2 equal sub-ranges of the next (bottom) level. It results in “log2n” levels of recursion to reach a 1-long sub-range. One of the recursion branches is highlighted in dark.While K-merge sort always cuts the current range into K equal parts, it will require only “logKn” levels to bring the initial n-long input sequence to 1-long ranges:The complete “workspace” of the K-merge sort algorithm, when “K=4”. We see that every sub-range of a current level is divided into 4 equal sub-ranges of the next (bottom) level. That results in “log4n” levels of recursion to reach a 1-long sub-range. One of the recursion branches is highlighted in dark.Within K-merge sort, as the depth of recursion decreases, so does the overall number of value assignments. We can observe this with the help of the following diagrams: for ordinary merge sort, its complete workflow can be depicted like this:All levels of the merge sort algorithm, presented as lists of horizontal ranges. On a certain layer, values of 2 adjacent ranges are being repeatedly merged into a twice-as-long range of the upper layer. That’s why, when tracking the path of a certain input value, it will traverse from the bottom layer to the top layer, being assigned a number of times proportional to “log2n” (the cyan curved path).According to the figurative arrows, the number of times every value is assigned is proportional to “log2n”. Thus, the number of assignments during the entire algorithm becomes proportional to “n*log2n”, which makes the time complexity of merge sort O(n*log n).For the K-merge sort algorithm, the complete workspace becomes shorter:All levels of the 4-merge sort algorithm are presented as lists of horizontal ranges. Values of 4 adjacent ranges are repeatedly merged into a 4 times longer range of the upper layer. That’s why, when tracking the path of a certain input value, it will traverse from the bottom layer to the top layer, being assigned a number of times proportional to “log4n” (the cyan curved path).The number of times every value is being assigned now is proportional to “logKn”. Thus, the number of assignments during the entire K-merge sort becomes proportional to “n*logKn”.We might wonder why K-merge sort is not the default sorting algorithm and is not widely preferred over merge sort.The answer is that K-merge sort has also one drawback: merging ‘K’ sorted arrays requires more computation. When merging 2 arrays ‘A’ and ‘B’, at every step it is enough to compare the next value of ‘A’ with the next value of ‘B’, and copy the smaller one into the result. That’s why the code of the merge routine observed earlier was that short.While when it comes to K-merge, in order to understand which value should go next to the result array ‘Out’, we should do more comparisons. Let’s assume “K=4”, so we are doing “4-merge”. To pick the smallest value from the next 4 input ones - “A[i]”, “B[j]”, “C[k]”, and “D[l]”, we should perform 3 comparisons now (please don't confuse the lowercase 'k', which is the index over array 'C', with the uppercase 'K', which is the number of parts the sequence is being split into):During the 7-th step of 4-merge of sequences ‘A’, ‘B’, ‘C’, and ‘D’, having the indexes over them as “i=2, j=1, k=2, l=1”, we see that “C[k]==23” is currently the smallest from value from “{A[i], B[j], C[k], D[l]}”, so we copy it to the output sequence ‘Out’, and advance only the index ‘k’ (together with the output index ‘m’) to prepare for the next step. Note that figuring out the smallest value here requires several comparisons, and not just 2.The code of the 4-merge procedure turns out significantly longer:We see that along with the nested conditions, always 3 comparisons are required to figure out the smallest head value between ‘A[i]’, ‘B[j]’, ‘C[k]’ and ‘D[l]’. Generalizing, at every step the K-merge sort performs “K-1” comparisons to find the smallest one from the ‘K’ current head values.The cost of doing more comparisons compensates the advantage of making fewer assignments. That is the reason the simpler merge sort is preferred over K-merge sort in practice. However, K-merge sort might be preferred in other circumstances, for example in external sorting (sorting outside of the RAM), where the cost of comparing 2 entries is much less than the cost of copying (or moving) them.Actually, there is one more approach too for merging ‘K’ sorted arrays. There, all the current head values are stored in a specialized data structure, like a priority queue, which enables fast retrieval of the smallest head value in O(1) time, and its substitution with the next value in O(log K) time. A detailed description of this approach can be found at [4]. However, using such sophisticated structures always introduces significant overhead. For example, if the priority queue is implemented as a binary heap, the overhead will come from:making swaps during sift-up and sift-down operations,checking not to go beyond the physical range of the tree, and finally,allocating necessary space in dynamic memory.That is the reason why a priority queue is generally not used for merging only a few (“K=3” or “K=4”) sorted sequences, as the mentioned overhead will certainly exceed possible gain in performance. Using a priority queue is justified when merging at least dozens of sorted sequences.···2. The guided merge procedureIn this article, I will describe the guided merge sort algorithm, which is based on the guided merge procedure. This is similar to how ordinary merge sort is based on the merge procedure. So we will discuss guided merge first.In fact, both guided merge and guided merge sort concepts belong to the approach where we divide the current range into ‘K’ equal parts, not 2. So, to be more precise, they should be called guided K-merge and guided K-merge sort respectively. However, sometimes I prefer to omit the prefix “K” to make the naming more compact and easily pronounceable.In this chapter we will observe the case when “K=4”, so we will be merging 4 sorted input sequences – “A”, “B”, “C” and “D”. As we already recalled, to do that K-merge algorithm repeatedly looks for the next smallest value between all the current heads (performing 3 comparisons per step), and appends it to the result sequence.What if we act differently? What if instead of looking for the next smallest value from scratch, we always keep in memory how the K current head values are ordered in relation to each other? In our example, at the very first step, those 4 head values are “A[0]”, “B[0]”, “C[0]”, and “D[0]”, and their relative ordering is:Relative ordering of the head values of the given 4 sequences, at the very beginning of the 4-merge procedure.Having this, it is straightforward that the initial smallest value is the leftmost one among them - “C[0]”, and it should be taken to the result sequence first. However, once “C[0]” is there and “C[1]” comes to substitute it during the next decision to make, the other 3 values preserve their relative order: “D[0] ≤ B[0] ≤ A[0]”, so “C[1]” will fit somewhere in between them or at the corners. The possible arrangements for "C[1]" are:“C[1] ≤ D[0] ≤ B[0] ≤ A[0]”, if the difference “C[1] – C[0]” was small enough, or“D[0] ≤ C[1] ≤ B[0] ≤ A[0]”, or“D[0] ≤ B[0] ≤ C[1] ≤ A[0]”, or, finally“D[0] ≤ B[0] ≤ A[0] ≤ C[1]”, if the difference “C[1] – C[0]” was large enough.So what we need to understand is: where exactly the next head value “C[1]” should be placed in the remaining sorted list “D[0] ≤ B[0] ≤ A[0]” to keep its sorted order. To figure that out, we will do a binary search for “C[1]” there. That is the key point of the guided merge algorithm. So, at first we will compare “C[1]” with the middle value of the sorted list: “B[0]”, and based on the result, next we will compare “C[1]” either with “D[0]” or with “A[0]”.In our example, “C[1] > B[0]” and “C[1] switch_threshold = 8switch_threshold = 16std::sort9452936093799073stl heap sort113286718112957752merge sort8098657684973511merge sort [over guided 2-merge]81728654863615083-merge sort8675432386948107guided 3-merge sort80238376803533214-merge sort9392397593648462guided 4-merge sort7853794278318971Benchmarking of different sorting algorithms, run on an n=50,000-long sequence of randomly generated dynamic arrays, each being 150-long and consisting of 64-bit integers. Blue bars correspond to a switch threshold of 8, while red bars correspond to a threshold of 16. All timings are presented in nanoseconds.And here are the timings of sorting 250-long static arrays of 64-bit integers. The length of the sequence being sorted is “n = 750’000” now:clobswitch_threshold = 8switch_threshold = 16std::sort41786000494205445303stl heap sort64990212746556292501merge sort42671968104406259873merge sort [over guided 2-merge]426502556244018183023-merge sort42103344374300471562guided 3-merge sort402514397641013608774-merge sort44299328964440996879guided 4-merge sort37648702703825355533Benchmarking of different sorting algorithms, run on n=750’000-long sequence of randomly generated static arrays, each being 250-long and consisting of 64-bit integers. Blue bars correspond to a switch threshold of 8, while red bars correspond to a threshold of 16. All timings are presented in nanoseconds.···7. ConclusionIn the current article, I have described the guided K-merge procedure and have derived the guided K-merge sort general-purpose sorting algorithm.The novelty here is in how the ‘K’ sorted sequences are being merged into one. In contrast to ordinary merge or K-merge procedures, guided K-merge doesn’t keep any helper information in containers, and instead uses “K!” isomorphic fragments of code, and jumps between them with the goto operator.This efficiently reduces the number of operations performed per step, making only ”log2K” comparisons, instead of the “K-1” comparisons of the K-merge procedure.The drawback of guided K-merge is that “K!” isomorphic fragments appear in the code. So, to avoid inflating the size of the program, picking values “K=3” or “K=4” promises the best balance between performance and the memory used.Implementation of the guided K-merge sort algorithm in C++ for cases “K=3” and “K=4” can be found on my GitHub at [5].If you’ll have any suggestions, questions, or will spot a mistake in the text, feel free to contact me by LinkedIn (the link below).Thank you so much for reading till the end!···My gratitude to:Elen Grigoryan, for careful design of all used illustrations (behance.net/elengrigoryansun),Meri Movsesyan, for detailed review of the article's draft (linkedin.com/in/mermovs/).If you enjoyed this article, feel free to contact me on LinkedIn (linkedin.com/in/tigran-hayrapetyan-cs/).All the images were designed upon request of the author.···References[1] - Sorting Algorithms, Part 1: Merge Sort, by Vyacheslav Efimov: https://towardsdatascience.com/merge-sort-explained-and-visualised-660f6946d9b5/[2] - Making Sense of Merge Sort [Part 1], by Vaidehi Joshi: https://medium.com/basecs/making-sense-of-merge-sort-part-1-49649a143478[3] - “Learn Merge Sort in 13 minutes”, by BroCode: https://www.youtube.com/watch?v=3j0SWDX4AtU[4] - “Direct k-way merge”: https://en.wikipedia.org/wiki/K-way_merge_algorithm#Direct_k-way_merge[5] – Implementation and benchmarking of guided K-merge sort in C++: https://github.com/tigranh/guided_merge_sort
Guided Merge Sort : An Optimized Sorting that Picks the Best from Ordinary and Multi-Way Merge Sort Algorithms
Full Article
Original Source
Read the full article at Towardsdatascience →KhanList aggregates and links to publicly available news content. We do not host full articles from third-party sources. Always verify important information with original sources.