
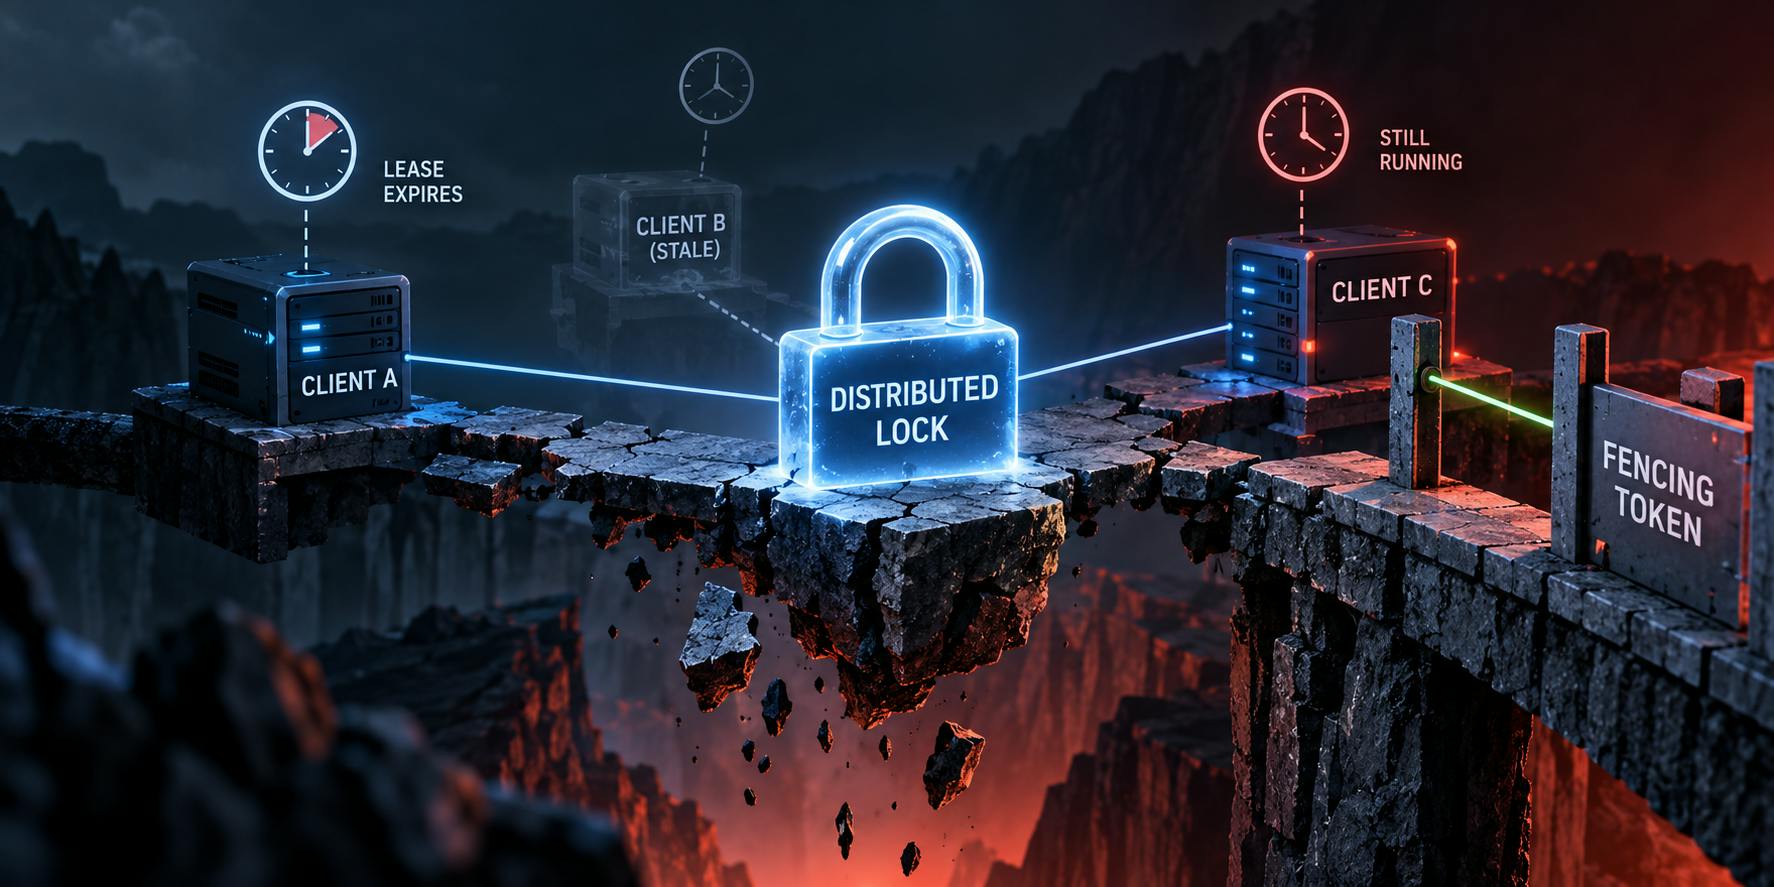
A distributed lock is not a bigger mutex A distributed lock is not a bigger mutex. It is a different animal wearing the same costume, and the costume is what gets people hurt. Distributed locks look deceptively similar to local mutexes. You acquire, you perform a critical operation, you release. That resemblance is dangerous. A local mutex lives inside one failure domain. A distributed lock spans processes and networks and clocks and storage, along with failure detectors that can disagree with each other. The lock service may correctly decide that ownership changed while the previous holder is still running or paused or partitioned, or while it is quietly carrying delayed requests. The central question is whether an obsolete client can still produce effects after its authority has ended. Martin Kleppmann frames the same divide as locks used for efficiency versus locks used for correctness. In the correctness case duplicate execution becomes corruption rather than wasted work. A lock is not a critical section Consider a lease-backed lock around a reconciliation job. Lease lease = lockService.acquire("order:" + orderId, Duration.ofSeconds(15)); try { reconcile(orderId); } finally { lockService.release(lease); } The code is locally reasonable and globally unsafe. Suppose the process pauses for 30 seconds after acquisition. Maybe garbage collection stalls it, maybe the CPU is starved, maybe it is paging, maybe something sends it a stop signal. The lease expires, another worker acquires the lock, and the original process later resumes. Nothing in the resumed process proves that authority still exists. A delayed network request creates the same failure even when the process never pauses at all. Checking the lease immediately before a write does not close the race, because execution can pause in the gap between the check and the write. Kleppmann uses this stale holder problem to show why even a perfect lock service does not automatically make protected resource access safe. Coordination systems can provide strong ownership semantics without controlling the resource that actually matters. The ZooKeeper lock recipe uses ephemeral sequential znodes and gives the lock to the client with the lowest sequence number. etcd ties lock ownership to a lease and releases the lock when that lease expires. Those mechanisms establish authority inside the coordinator. They do nothing to stop an old process from writing to an external resource after ownership has changed. Leases trade deadlock for stale ownership Leases exist because permanent locks have a severe liveness problem. A crashed owner can block progress forever. Time-bounded authority lets another participant proceed after expiration, but now time becomes part of the safety argument. Redis Redlock computes a remaining validity window from the elapsed acquisition time and assumes local clocks progress at roughly the same rate with bounded drift relative to the TTL. Current Redis documentation also warns that TTL expiration does not use a monotonic clock, and that a shift in the wall clock can compromise consistency. Lease expiration is not necessarily a single instant that everyone observes at once. Consul documents TTL as a lower bound for invalidation. Expiration will not occur before the TTL, but it may occur later. Consul warns about clock skew too. More fundamentally, it notes that failure detection can produce false positives and release a lock while the owner is still alive. Disabling those checks improves safety at the expense of liveness. Faster failure detection improves progress but raises the risk of overlapping authority. Lease renewal reduces probability, not category. Extending a TTL helps a long-running operation, but it cannot make networks timely, or process pauses bounded. Redis documentation now states that lock retention must not be assumed merely because the owning process is still alive, and it recommends fencing tokens for work that runs long. Fencing moves safety to the resource A fencing token is a monotonically increasing value issued whenever ownership changes. Every protected operation carries that token. The resource remembers the highest token it has accepted and rejects any request carrying an older value. This converts a timing problem into an ordering problem. A stale process may resume, and an old RPC may arrive late, but neither one can overwrite state once a newer owner has advanced the fence. The essential logic belongs at the write boundary, not only in the lock client. long token = lockService.acquire("account:" + accountId).fencingToken(); int updated = jdbc.update(""" UPDATE accounts SET state = ?, fence_token = ? WHERE id = ? AND fence_token <= ? """, state, token, accountId, token); if (updated != 1) throw new StaleLockHolderException(); The database performs the comparison and the state change atomically. A request carrying token 41 cannot modify a row after token 42 has been accepted. The token has to be ordered and durable and scoped to the protected resource, and it must not be casually reset when the coordinator restarts. A random lock identifier is useful for safe release but it is not a fence, because randomness establishes identity rather than order. Redis uses random values to avoid deleting another client's lock, and separately recommends fencing for consistency. Several coordinators expose building blocks for this pattern. Consul increments LockIndex on acquisition and documents the triple of (Key, LockIndex, Session) as a sequencer that can identify a stale request. ZooKeeper sequential nodes provide monotonically increasing sequence suffixes. etcd exposes creation revisions for election leadership and supports transactionally testing that the leadership revision still matches. The important property is not which coordinator you picked. It is whether the downstream resource actually enforces the ordering information. Failure modes survive correct acquisition Correct acquisition can still coexist with unsafe effects. A partition can prevent renewal while leaving access to the protected database intact. A lock server can fail over while an application thread stays paused. A retry can duplicate a side effect that was never idempotent. A fencing token can be generated correctly and then ignored by one write path. It can be compared without atomicity, or stored only in memory, or reused after a restore, or scoped to the wrong thing. These are protocol failures rather than lock library bugs. Consul makes the advisory nature explicit. Its lock does not itself stop clients from reading or writing the underlying key without ownership. Some effects cannot naturally enforce fencing. Email delivery, a third-party API, or a legacy device may not expose a conditional operation that rejects a token lower than X. Correctness then has to move to a boundary that can reject duplicates or conflicting state. Idempotency keys can make a retried API request safe when the service supports them, and a database uniqueness constraint can reject a duplicate state transition represented by the same key. A distributed lock cannot retroactively make an unfenceable side effect exclusive. Testing has to attack stale authority rather than only lock contention. Useful fault injection pauses a holder beyond its TTL. It partitions the holder from the coordinator but not from storage. It delays writes until after reassignment, restarts the coordinator, forces renewal to fail, and reorders retries. The acceptance criterion is stronger than observing that only one lock owner was recorded. The protected resource must reject effects from every superseded epoch. These scenarios follow directly from the documented risks around lease expiration, false failure detection, and delayed execution. The lock is only half the protocol Distributed locks are safest when you treat them as advisory coordination plus an explicit mechanism for effect safety. Leases restore liveness by letting ownership expire, but expiration is exactly what creates stale holders. Consensus-backed coordinators improve the authority decision, yet they cannot erase a paused process or a delayed packet. Fencing tokens close that gap only when the protected resource validates them atomically and durably. Where fencing is impossible, something else has to carry the correctness burden, whether that is idempotency, a transaction, or a redesign. The dangerous distributed lock is not the one that occasionally fails to acquire. It is the one that looks successful while obsolete authority can still mutate reality.
Distributed Locks Are More Dangerous Than They Look
Full Article
Original Source
Read the full article at Hackernoon →KhanList aggregates and links to publicly available news content. We do not host full articles from third-party sources. Always verify important information with original sources.