
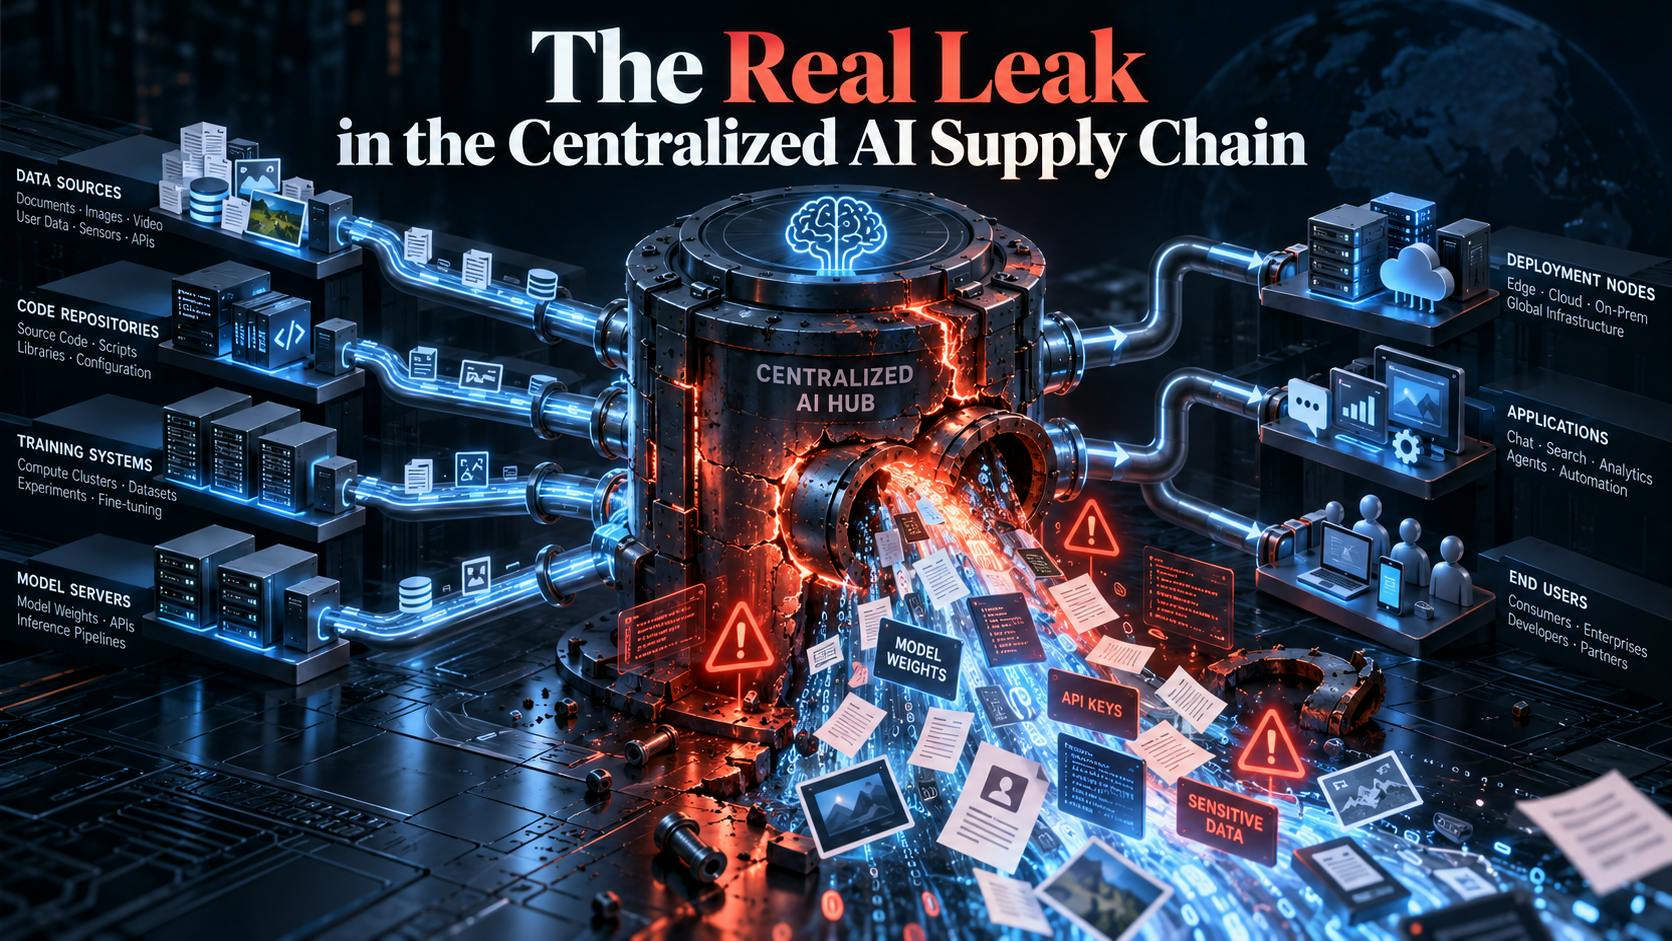
Why data sovereignty, model portability, and verifiable failover matter more than choosing between centralized and decentralized AI.Imagine your AI-powered product is growing steadily. Then your inference provider changes its pricing, retires a model, restricts regional access, or experiences an outage.Your application still works. Your code is intact. Your customers are ready. But a critical part of your infrastructure is no longer under your control.This is one of the most important architectural risks in modern AI: a system can be technically operational yet commercially dependent on infrastructure it cannot readily replace.Decentralized AI offers interesting alternatives. But decentralization alone does not solve the problem. The stronger goal is operational sovereignty: the ability to control sensitive data, evaluate substitute models, and change infrastructure without rebuilding the entire product.The Real Vulnerability Is Concentrated DependencyAI dependency extends beyond API access. It includes data governance, model behavior, operational continuity, and cost predictability.Consider three examples.Data exposure. In 2023, Samsung employees were reported to have uploaded sensitive company information, including source code, into ChatGPT. The incident highlighted the risks of transmitting confidential information to external AI services without appropriate controls. It does not, by itself, establish that the information was reproduced to other users.Regulatory uncertainty. Italy's data-protection authority announced a €15 million penalty against OpenAI in December 2024. However, a Rome court ruling published on March 18, 2026, upheld a challenge against the authority's decision. The broader lesson is not that one vendor was permanently penalized, but that AI data-processing arrangements can create changing legal and compliance obligations.Operational dependency. Model retirement, service interruption, changing usage policies, and unpredictable demand can force developers to modify systems they expected to remain stable.These examples represent different failure modes. They should not be treated as equivalent, but they reveal the same architectural question: What happens when an external dependency changes faster than your organization can respond?Portability Is a Better Starting Point Than IdeologyCentralized inference has substantial advantages: mature infrastructure, managed scaling, integrated tooling, and potentially strong service commitments.Decentralized compute can offer alternative sourcing, distributed capacity, and greater flexibility in infrastructure selection.Neither approach is automatically superior.A decentralized GPU marketplace introduces its own challenges: variable hardware, network performance, provider trust, workload confidentiality, and uncertain service guarantees.The objective should therefore be to reduce concentrated dependency without introducing unnecessary operational complexity.A sovereign AI architecture needs four distinct capabilities:Data control: sensitive information remains subject to enforceable access, retention, and deletion policies.Model portability: alternative models can perform required tasks within acceptable quality limits.Infrastructure substitutability: approved inference backends can be changed without major application rewrites.Operational verification: the organization can demonstrate that migration or failover actually works.These capabilities can be implemented using cloud infrastructure, private deployments, open-weight models, decentralized compute, or combinations of them.The architectural property matters more than the label.Building a Portable AI StackLayer 1: Separate the Application From the Model ProviderStart with an internal inference gateway. Instead of connecting every application component directly to one vendor, expose a controlled interface that handles model selection, authentication, routing, and policy enforcement. Open-weight inference engines such as vLLM can expose OpenAI-compatible endpoints, including /v1/chat/completions. This compatibility reduces integration work, but it does not guarantee identical behavior. Different models can vary in structured output, function calling, context handling, latency, and instruction following. A successful migration therefore requires behavioral compatibility tests—not merely a working HTTP request.Layer 2: Introduce Approved Compute AlternativesA second backend might use private GPU infrastructure, a different managed provider, or a decentralized compute platform.Nosana is one example of a decentralized GPU compute network worth evaluating.However, its inclusion in an architecture should depend on measurable requirements rather than assumptions about lower prices or greater resilience. Evaluate candidate backends against workload-specific criteria: inference quality, tail latency, effective cost, availability, data-handling assurances, and operational recovery. For confidential workloads, a provider must pass security and authorization checks before receiving production data.More providers do not automatically mean more resilience. They can also mean more trust boundaries.Layer 3: Keep Sensitive Memory Under Explicit GovernanceAn AI system's operational memory can contain personal details, customer records, credentials, proprietary documents, and commercially sensitive information.Automatically writing these records to permanent decentralized storage would create serious governance problems.Instead, sensitive prompts and agent memory should reside in appropriately protected storage with encryption, scoped access, retention controls, and deletion procedures.Decentralized storage technologies such as Arweave may be relevant for public artifacts, integrity evidence, or carefully designed encrypted data workflows.They should not become the default destination for private conversation histories. Ownership is not established simply by putting information on a blockchain. Meaningful control requires enforceable authorization, lifecycle management, and an understood threat model.Layer 4: Decouple Tools and Agent IntegrationsThe Model Context Protocol (MCP) provides a standardized way for applications and AI systems to interact with external tools and contextual resources.This can reduce integration coupling. But MCP is not a universal model-portability protocol. It does not automatically migrate fine-tuned weights, reproduce model behavior, or guarantee tool-use security.Tool permissions, trust boundaries, input validation, and execution authorization remain separate engineering responsibilities.A portable system must preserve these controls when models or infrastructure change.The Failover Router Is a Security BoundaryA common recommendation is to maintain a list of inference providers and send requests to whichever endpoint is currently available.That is insufficient for production use.An inference gateway needs to distinguish between availability and authorization. For example, a public research summarization request may be eligible for several approved providers. A confidential customer document may be restricted to a private deployment. If the private backend fails, automatically forwarding that document to an external GPU network could convert a service outage into a data-security incident.A safer routing policy follows this sequence: Classify the workload → identify authorized backends → verify compatibility → check health → select a backend → execute with timeout and bounded retry → record an auditable result.For requests that have side effects, retry behavior must also account for idempotency and duplicate execution.An illustrative policy could look like this:route(request): policy = classify(request) candidates = authorized_backends(policy) candidates = filter_by_capability(candidates) candidates = filter_by_health(candidates) if candidates is empty: return controlled_unavailable backend = select_by_policy_and_cost(candidates) result = execute_with_timeout(backend, request) if result is retryable_failure: fallback = next_authorized_backend(candidates) if fallback exists and retry_is_safe(request): result = execute_with_timeout(fallback, request) audit_outcome(result) return result This is architectural pseudocode, not a tested implementation. Real deployments require authentication, network isolation, secure configuration, retry budgets, request validation, and observability.The crucial principle is simple: failover must preserve the original data-security policy.Prove Portability With a Vendor Exit DrillAn architectural diagram can show where substitution should happen. It cannot prove that substitution will succeed.A more useful test is a controlled vendor exit drill. Select a representative set of workloads, then simulate the primary inference provider becoming unavailable.Measure the following:MeasurementQuestionRecovery timeHow long until the application resumes acceptable service?Quality regressionHow much does output quality change on fixed evaluation cases?p95 latencyHow does the alternative affect response time?Total operating costWhat is the full cost of using the fallback, including infrastructure and operations?Data exposureDid any request cross an unauthorized trust boundary?Portability coverageWhat proportion of required workflows still functions correctly?The test should include ordinary requests, structured outputs, tool calls, sensitive workloads, and failure scenarios. Pass criteria must be defined before the exercise.For example, a security-sensitive workflow might prohibit external fallback entirely. In that case, a controlled refusal or temporary outage is a successful policy outcome—not a portability failure. This distinction is essential: the goal is not to keep every request running at any cost.The goal is predictable, policy-compliant continuity.Where Decentralized AI FitsDecentralized infrastructure becomes valuable when it improves a measurable property of the system. A distributed GPU marketplace might increase sourcing flexibility. Portable model deployment could reduce dependence on a particular managed service. Verifiable records might strengthen auditability for appropriate artifacts.But those benefits must be compared against additional networking, security, performance, governance, and integration costs.A practical hybrid architecture might use:Private inference for confidential workloads.Managed cloud inference for applications requiring specific capabilities or service levels.Approved decentralized compute for suitable non-sensitive or separately protected workloads.Portable application data and evaluation suites across every environment.These are design possibilities, not universal recommendations. An organization should adopt each component only where its measured benefits justify the additional complexity.The Hard Problems Are Still UnsolvedOpen-weight models improve deployment flexibility, but a model's license, hardware requirements, and serving behavior can still constrain migration.Open APIs reduce integration friction, but they cannot guarantee functional equivalence between models. Decentralized compute can diversify supply, but that does not automatically provide production-grade latency, confidentiality, or availability guarantees. And permanent storage introduces difficult tensions with privacy, correction, and deletion obligations.These limitations should shape deployment decisions rather than be treated as implementation details to solve later.What Teams Should Do NextFor CTOs and engineering leaders, begin by mapping the points where a single AI provider controls an essential capability. Identify which dependencies are contractually protected and which can actually be replaced.For developers, introduce a provider abstraction only where it solves a demonstrated dependency. Maintain compatibility tests, approved routing policies, and a repeatable deployment process.For security teams, treat every alternative inference endpoint as a separate trust boundary. Review data residency, confidentiality, authorization, logging, and failure behavior before enabling production traffic.For researchers, compare centralized and decentralized inference using reproducible workloads, quality evaluations, tail-latency measurements, total cost, and clearly documented limitations.The most useful question to ask is not, "Is our AI decentralized?"It is: If our primary AI provider became unavailable tomorrow, which parts of our system could we recover, how quickly, at what cost, and without violating our security obligations?If your team can answer that question with evidence, you are already making progress toward meaningful AI sovereignty.Looking Toward 2030By 2030, AI infrastructure could become substantially more interchangeable, with portable agent configurations, user-controlled data stores, and a wider range of inference providers.That is a possible future, not an established forecast. Its success will depend on interoperability standards, security assurance, enforceable governance, and credible performance measurement—not simply on moving computation or storage onto decentralized networks.The future worth building is one where AI users have meaningful choices, and developers can change providers without surrendering reliability, privacy, or control.AI sovereignty is not the absence of centralized infrastructure. It is the ability to make infrastructure choices without being trapped by them.ReferencesBloomberg, May 2023 — Samsung's restrictions on generative AI following employees' disclosure of sensitive information: https://www.bloomberg.com/news/articles/2023-05-02/samsung-bans-chatgpt-and-other-generative-ai-use-by-staff-after-leakGarante per la protezione dei dati personali — OpenAI investigation, original sanction announcement, and notice of the March 2026 court ruling: https://www.garanteprivacy.it/web/guest/home/docweb/-/docweb-display/docweb/10085432vLLM documentation — OpenAI-compatible serving interfaces: https://docs.vllm.ai/en/latest/serving/openai_compatible_server/Model Context Protocol — https://modelcontextprotocol.io/Nosana documentation — https://learn.nosana.com/Arweave — https://arweave.org/
An Architecture for AI Sovereignty Across Models and Compute Providers
Full Article
Original Source
Read the full article at Hackernoon →KhanList aggregates and links to publicly available news content. We do not host full articles from third-party sources. Always verify important information with original sources.